home
diamond Go Premium
Data Engineering Path  ·  Airflow
Apache Airflow Logo
AWS CORE PLATFORM CASE STUDY

Lambda Operators & Hooks

The Escape Hatch for "Just Run This Small Thing"

Not every step in a pipeline deserves a full operator, a container, or a dedicated compute cluster. When you need a small, fast, stateless piece of logic — a light transform, a validation check, a call to an internal API — invoking an existing Lambda function is often the cheapest and simplest option.


The Operator

from airflow.providers.amazon.aws.operators.lambda_function import LambdaInvokeFunctionOperator

invoke_fn = LambdaInvokeFunctionOperator(
    task_id="invoke_processing_function",
    function_name="sales-data-validator",
    payload='{"table": "orders", "date": "2026-09-04"}',
    aws_conn_id="aws_default",
)

LambdaInvokeFunctionOperator supports both invocation types:

invocation_type Behavior
RequestResponse (default) Synchronous — the task waits for the function to return, and the response becomes the task's XCom output
Event Fire-and-forget — the task succeeds as soon as the invocation is accepted, without waiting for the function to finish

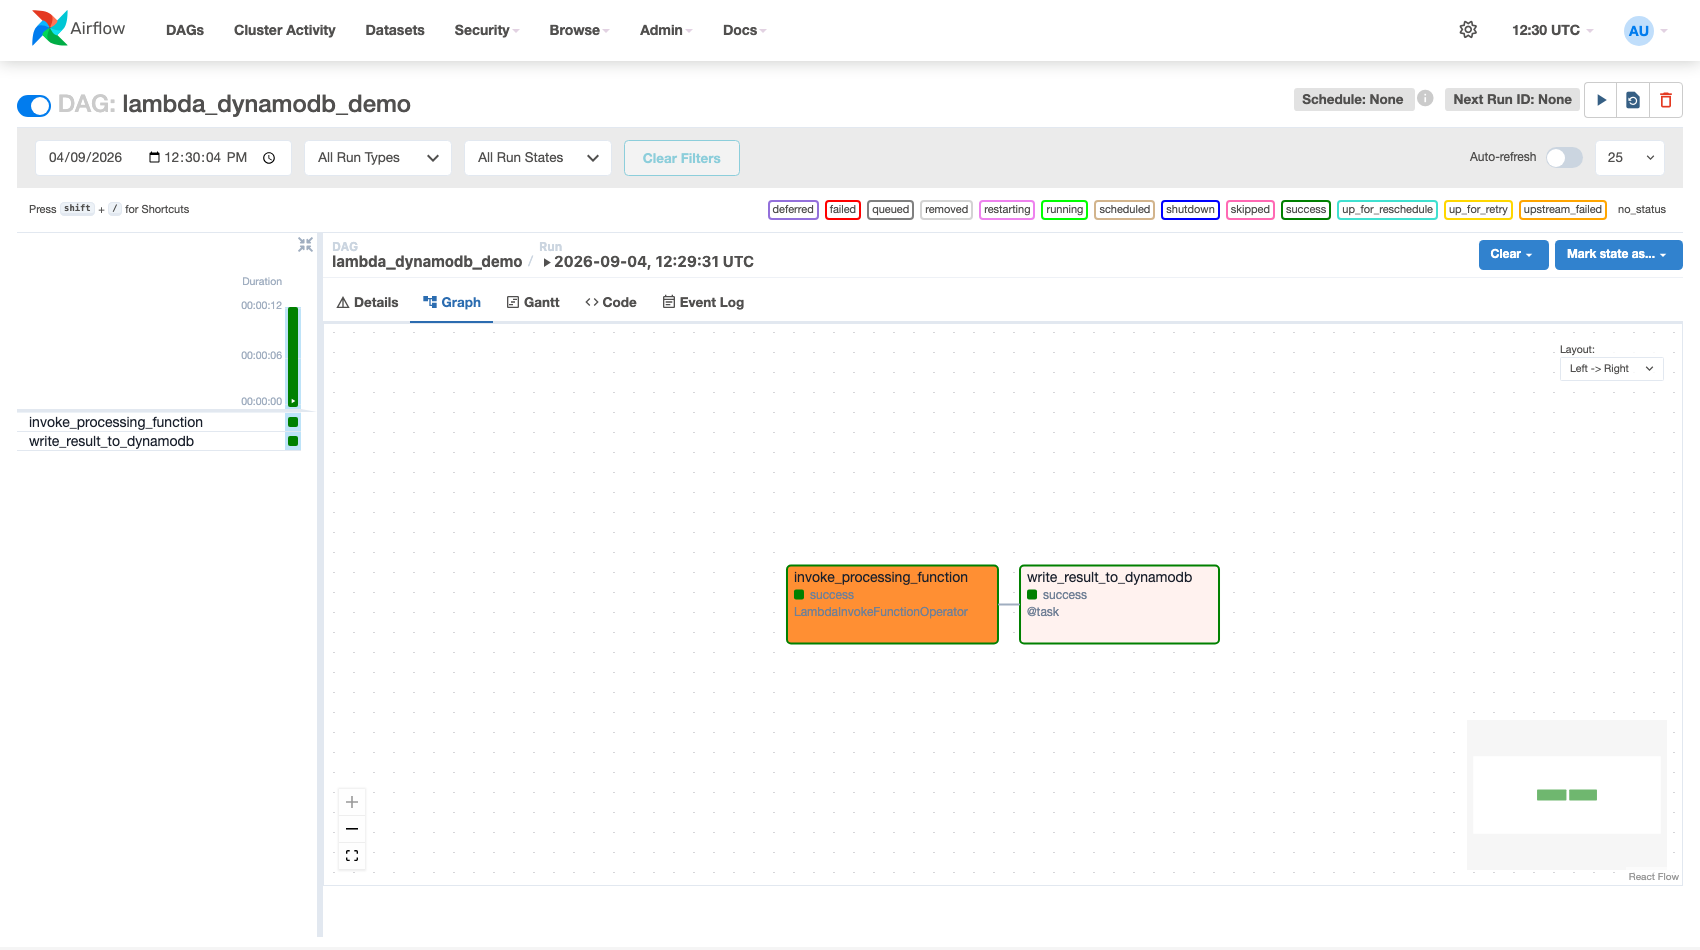
Run for real, invoking a live Lambda function and passing its response downstream via XCom:

Airflow Graph View — LambdaInvokeFunctionOperator succeeding, followed by a downstream task consuming its response Figure — a genuine synchronous Lambda invocation; the second task receives the actual response payload through .output.


The Hook Directly

from airflow.providers.amazon.aws.hooks.lambda_function import LambdaHook

def invoke_with_retry_logic(**context):
    hook = LambdaHook(aws_conn_id="aws_default")
    response = hook.invoke_lambda(
        function_name="sales-data-validator",
        payload='{"table": "orders"}',
    )
    return response["Payload"].read().decode()

Reach for the Hook directly when you need custom error handling around the invocation (e.g., a specific retry policy for TooManyRequestsException throttling) that the operator's built-in retries don't cover.

Don't Use Lambda as a Substitute for Spark
Lambda has a hard 15-minute execution ceiling and limited memory/ephemeral storage. It's the right tool for small, fast, stateless logic — not for processing large datasets. If a task needs real compute, delegate to Spark/EMR/Glue instead; use Lambda for the glue code around them, not the heavy lifting itself.
lock

This content is reserved for Premium Members.

Upgrade to Premium

Entity Details

Create New Item

help

Submit Technical Query

Have a question or run into an issue? Describe it below, upload an optional screenshot, and our engineering team will answer it!

image Attach image (optional)

Submit Feedback

build Free Developer Utility Free Tool
gavel

Privacy & Legal Disclaimer

1. Client-Side Browser Processing

All utility tools on DeepEngineerHub (including Image to PDF, Text Formatters, JSON Converters, and Encryptors) execute 100% locally within your client browser using WebAssembly and JavaScript. No uploaded images, text, or documents are transmitted, collected, or stored on remote servers.

2. Limitation of Liability ("As-Is" Provision)

Tools and services are provided free of charge for convenience and educational purposes "as-is" without warranties of any kind. DeepEngineerHub shall not be held liable for any data loss, formatting inconsistencies, or indirect damages resulting from tool usage.

3. Open Source & Third-Party Software

Certain utilities utilize open-source client libraries (such as jsPDF, Mermaid.js, Pyodide) licensed under MIT, Apache, or BSD open licenses. All intellectual property remains with their respective copyright holders.